
Model fine-tuning through reinforcement learning is fast becoming one of the most demanding jobs in AI infrastructure. It mixes training, inference and sandboxed agent work in a single loop, often with research code tangled into the systems beneath it.
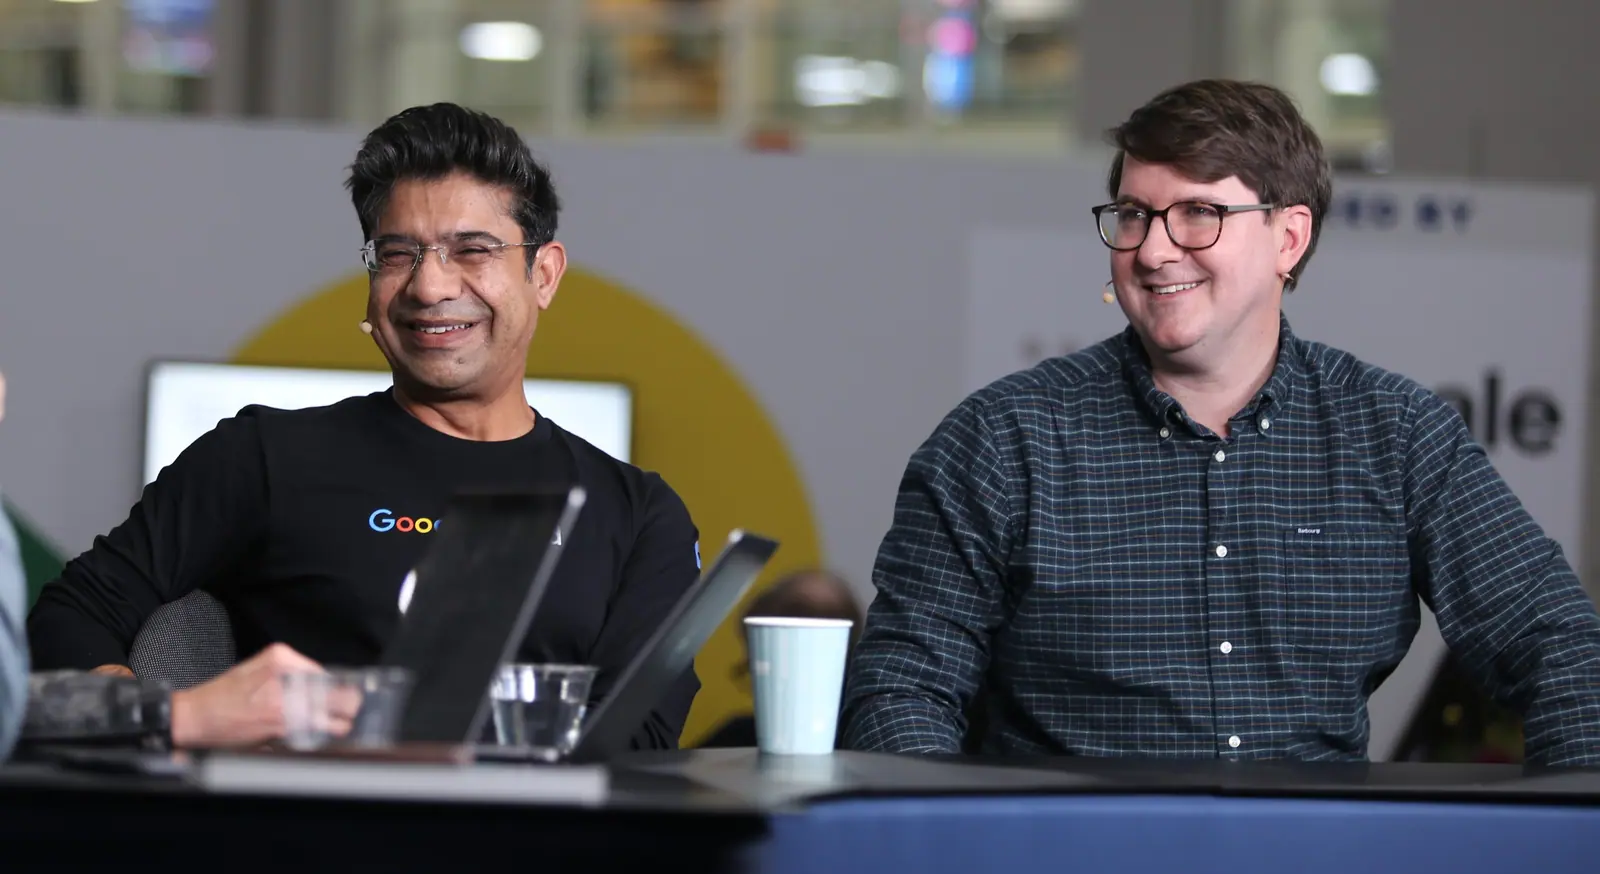
Google LLC has been tackling that problem from inside its Kubernetes engineering group, and recently donated the result, OpenRL, to the Cloud Native Computing Foundation. The GKE Labs team got there by building an AI agent for Kubernetes tasks, then a benchmark to grade models on that work, according to Sunil Arora (pictured, left), senior software engineer at Google Cloud.
“If you look at reinforcement learning, I think of it as a kind of a super app of AI because it involves training. It involves sampling. It involves agents actually doing things in a sandbox and sometimes kind of evaluating the work,” Arora said. “It’s kind of a very diverse workload and it is, I think, pushing the boundaries of our infrastructure.”
Arora and Justin Santa Barbara (right), developer at Google, spoke with theCUBE Research’s John Furrier and Rebecca Knight at KubeCon + CloudNativeCon NA, during an exclusive broadcast on theCUBE, SiliconANGLE Media’s livestreaming studio. They discussed model fine-tuning and their work in GKE Labs, which puts experimental projects in users’ hands early. (* Disclosure below.)
Model fine-tuning without the infrastructure tangle
OpenRL debuted as a research preview in June 2026, offering a self-hosted training API for a company’s own Kubernetes cluster. It splits the reinforcement learning loop from the compute plumbing, so infrastructure engineers handle scaling while researchers keep control of experiments, Arora explained.
“With OpenRL, one of the things that we are trying to do is kind of abstracting away the infrastructure as kind of core primitives so that researchers and AI engineers can just focus on their RL loop,” Arora said.
Sandboxes are where that loop meets agent infrastructure, since calculating rewards can mean running millions of isolated commands. Google’s Agent Substrate packs more of those sandboxes onto limited compute, according to Arora. For Santa Barbara, the need surfaced one step at a time.
“We built kubectl-ai, and in theory, kubectl-ai could have formatted my hard disk,” Santa Barbara said. “I would quite like a sandbox for this so that if it formats a hard disk, it formats that sandbox and no damage.”
Here’s the complete video interview, part of SiliconANGLE’s and theCUBE’s coverage of KubeCon + CloudNativeCon NA:
(* Disclosure: Google Cloud sponsored this segment of theCUBE. Neither Google Cloud nor other sponsors have editorial control over content on theCUBE or SiliconANGLE.)
Photo: SiliconANGLE