
For most of its history, the high-performance computing market measured progress the same way: how fast a machine could solve a fixed problem. Rankings rose, a new system took the top spot, and the cycle started over. Raw performance remains the foundation of scientific computing, and Nvidia Corp. brought plenty of it to SC26.
But this week, Nvidia argued that speed at solving a single problem is no longer the right way to measure leadership. An equally important question now is how many times a researcher can go from hypothesis to result in a day, and what happens when the “researcher” is an artificial intelligence agent that never sleeps.
That idea ties together Nvidia’s bevy of announcements at the show. The company introduced open science models, a CPU-only supercomputing rack, a new HPC-specific GPU, a batch of CUDA-X libraries, quantum integration for the Slurm workload manager, a quantum co-design platform with IBM and Fermilab, and a co-packaged optics deployment at Lambda. It also marked CUDA’s 20th birthday.
Taken individually, these announcements look like a typical supercomputing show news payload. Taken together, they describe a stack built for a different user, namely the AI agent that reasons through a scientific problem, calls a simulation, reads the result and decides what to try next.
The news in brief
Here’s a summary of what Nvidia announced:
- Nemotron for Science packages the open Nemotron 3.5 Super VL model with LitmusBench v0.2, a new open dataset of nearly 50,000 chemistry-reasoning questions, and post-training recipes for building domain-specific science agents.
- The Vera CPU rack-scale platform packs 192 Vera CPUs, about 300TB of memory, and Quantum-X800 InfiniBand into a liquid-cooled rack designed for unaccelerated workloads, including climate and molecular modeling. Dell, HPE, Lenovo and Supermicro will ship it starting in early 2027.
- Rubin HPC is a new GPU in the Vera Rubin family, featuring more than 50,000 CUDA cores and sparse-data acceleration, with a 2028 release.
- New CUDA-X libraries, including cuPhoton, cuPotential and cuSpa, target applications across astrophysics, drug discovery, materials science and single-cell biology.
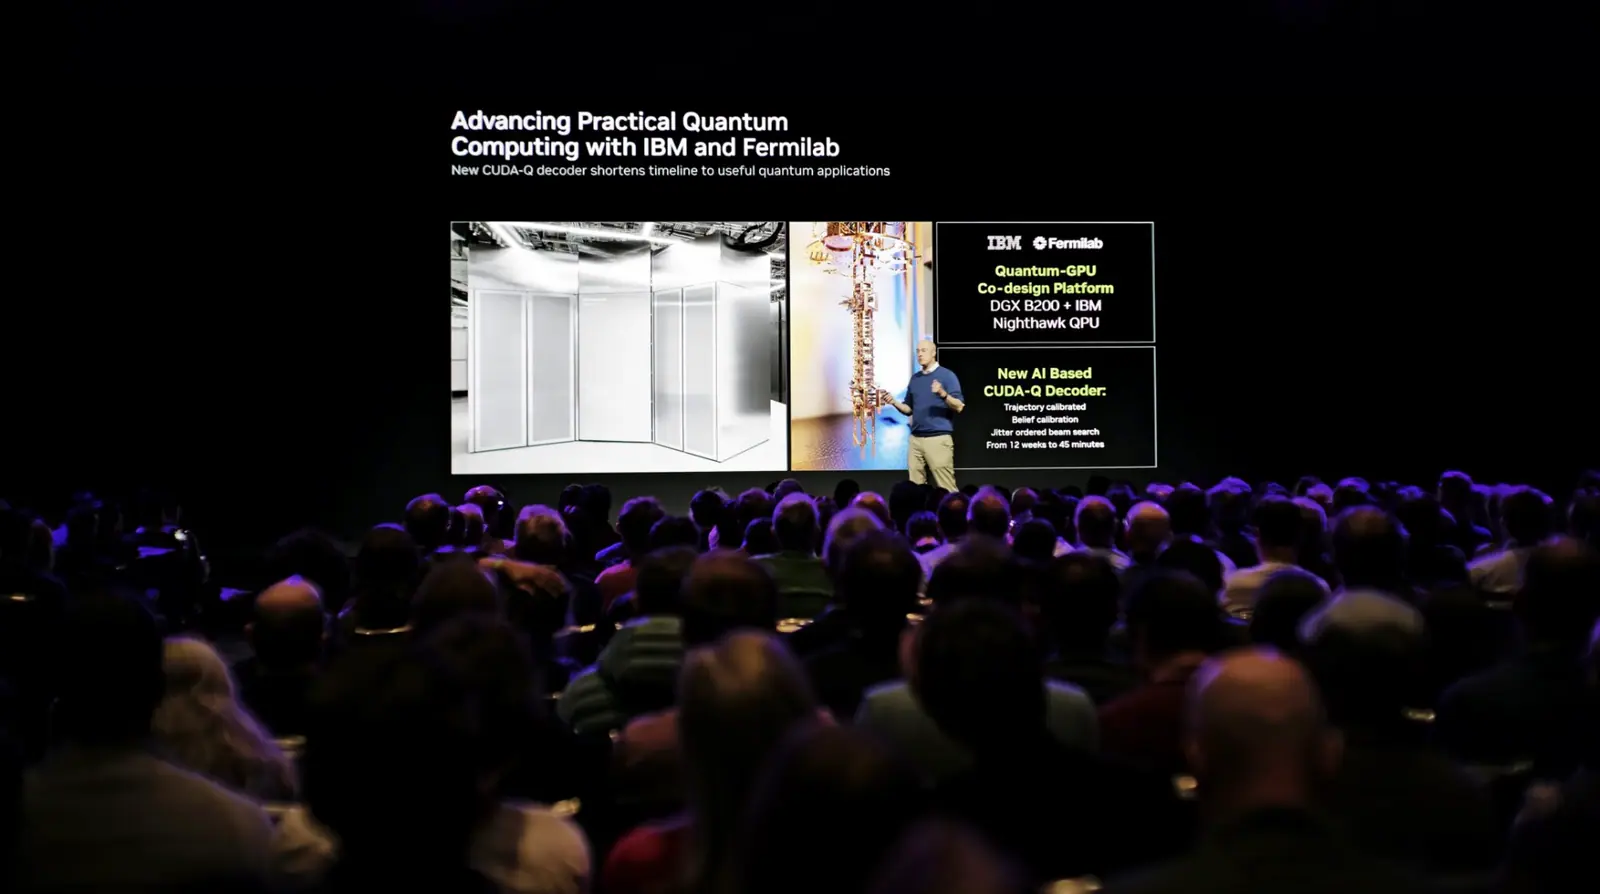
- Quantum: A modular codesign platform with IBM and Fermilab, a new error-correction decoder and quantum scheduling support in Slurm.
- Lambda is using Nvidia Photonics co-packaged optics switches to connect GB300 NVL72 racks that house more than 10,000 GPUs.
While each announcement is interesting, the more compelling story is what they reveal about where scientific computing is headed. I see five themes.
Theme 1: The loop is the new benchmark
Ian Buck (pictured), Nvidia’s vice president of hyperscale and high-performance computing, summed up this thesis when introducing Rubin HPC: “For agents tackling science and engineering, faster simulation means faster discovery.” This marks an important industry shift. Simulation used to be the end product. In an agentic workflow, it’s a tool call within a much larger loop of hypothesis, simulation, and refinement.
When an agent can generate thousands of candidate molecules or material designs, the bottleneck shifts from ideas to the time required to test them. That’s why so much of the SC26 news focuses on loop speed alongside peak flops. Nvidia says cuPhoton cut the time to correlate Event Horizon Telescope black-hole data from more than a month to eight minutes.
At Pacific Fusion, a Nemotron-powered agent running on the same system can analyze plasma simulations as they run, allowing researchers to steer the simulation in real time rather than waiting for it to finish. Lawrence Berkeley National Laboratory is using Nvidia’s DAQIRI networking library to move electron-microscopy analysis into the experiment itself, so researchers can decide what to measure next while measurements are being taken.
All of these share the same idea: Shrink the gap between asking a question and getting enough of an answer to ask a better one. For researchers, this should change how they evaluate infrastructure. Single-job time-to-solution is an important metric, but time-to-insight per iteration is equally important and should be tracked.
Theme 2: Small, specialized and open beats big and general for science
The most important data point at SC26 may have come from a startup, not a supercomputer. Lila Sciences post-trained Nemotron with lab feedback, nearly doubling its accuracy on quantum-dot synthesis protocols to 61%, beating GPT-6 Astra’s 54% at what Nvidia states is 10 to 20 times lower inference cost. Therna nearly doubled accuracy over frontier models in predicting mRNA protein-expression ranges. Terray Therapeutics trained the model to extract reactants, products, and conditions from chemistry diagrams.
That’s consistent with what I’ve been hearing across my enterprise clients: frontier models are a great starting point, but domain-tuned open models often win on accuracy and economics in specialized fields. Science pushes this further than most industries for three reasons. Research data is often proprietary or regulated. Experimental feedback serves as a training signal that general-purpose models lack. Labs want models running on infrastructure they control.
That last point is why Nvidia optimized Nemotron 3.5 Super VL to run on a 128GB DGX Spark. KTH Royal Institute of Technology reports that an agent built on it fixed 81% of broken GROMACS molecular-dynamics setups in a single overnight run on a single Spark.
Nvidia releasing the dataset and the recipes, not just the weights, is important here because the model is a commodity, but the know-how to adapt it is what research teams have lacked.
Theme 3: Nvidia wants every processor and the scheduler that runs them
Nvidia is well-known as the industry’s top GPU provider, but it also offers a CPU rack with Vera. Nvidia is now targeting the part of HPC that has never been accelerated, a market x86 has owned for decades. In Nvidia’s own testing, Vera delivered 1.9 times the performance and 2.4 times the performance per watt of x86 on an OpenFOAM airflow simulation.
DKRZ, the German Climate Computing Center, has selected Vera for its HLRE-5 system. The new Fortran compiler beta isn’t all that sexy, but it’s an important piece. Huge amounts of scientific code are written in Fortran, and nobody wants to rewrite it. Removing that friction is how a CPU challenger takes share.
Across the portfolio, Vera handles CPU-bound simulation. Rubin HPC is built for sparse, memory-bound science rather than AI training. DGX systems sit alongside IBM quantum computers. Nvidia is extending Slurm, the open-source scheduler most supercomputing centers already use, to schedule QPUs alongside CPUs and GPUs using familiar commands. Nearly 30 data centers are now deploying more than 50 quantum processors, and Alice & Bob, IBM, IQM, Pasqal and Quantinuum have adopted the expanded Slurm.
Nvidia wants to be the company that coordinates whichever processor the agent needs next. An agent doing drug discovery might call a CPU-bound molecular dynamics job, a GPU-accelerated docking run, and eventually a quantum chemistry routine. The vendor that owns the orchestration owns the workflow. Owning the hardware still matters, but less so than before.
Theme 4: Quantum is becoming a systems problem
The quantum news deserves its own mention because the tone has shifted. Two or three years ago, vendors mostly talked about qubit counts. At SC26, the focus was on error correction, decoding, and integration, which are classical computing problems. Nvidia’s new TCBP-JOBS decoder, available in CUDA-Q QEC 0.9.0, delivers up to 13,000 times faster decoding for error-correction research and reduces some design studies from 12 weeks to 45 minutes. IBM and RIKEN’s hybrid quantum-classical chemistry work, which modeled protein-ligand complexes with up to 12,635 atoms, is a Gordon Bell Prize finalist.
IBM’s Jerry Chow discussed the opportunity: “Scaling quantum and classical together will open new frontiers in high-energy and nuclear physics and beyond.” Nvidia has long embraced a systems approach spanning a broad ecosystem of partners, and IBM adds to that. IBM doesn’t need Nvidia to build qubits; it needs accelerated classical computing to make those qubits useful. That’s a typical position for Nvidia, which becomes essential to quantum, regardless of which qubit approach wins.
Theme 5: Efficiency and resiliency are now science features
Energy used to be a facilities issue in HPC. Now it’s a research constraint because every watt spent on overhead is a watt not available for simulation. Nvidia’s Vera delivers twice the energy efficiency of x86 on the Weather Research and Forecasting model.
Lambda’s deployment demonstrates the same idea at the network layer. Across more than 10,000 GPUs, Lambda used co-packaged optics switches and observed network latency drop by about 4% at rack scale and up to about 10% at pod scale, with a median optics temperature of 36 degrees Celsius versus 51 degrees for pluggable optics. This approach is up to five times more power-efficient and up to 15 times more reliable than pluggables, and engineers can swap the light sources in the field.
As Nvidia’s blog notes, with agentic inference, a single network disruption can cause cascading latency across many agents. When the workload is a continuous loop rather than a batch job, uptime becomes a research metric. Lambda is also the first large-scale neocloud proof point for co-packaged optics, which I expect other GPU clouds will need to address.
The thread that holds it together: CUDA at 20
It’s fitting that Nvidia marked its CUDA software’s 20th anniversary at the same show. CUDA was introduced at SC06, and Nvidia reports that more than 11 million developers now build on it, with more than 1,000 CUDA-X libraries. From AlexNet to AlphaFold, the pattern has been the same: hardware draws attention, while libraries create lock-in.
The agentic era raises the stakes for that library catalog. A human scientist might know a handful of tools well. An agent can call any of them, so the size and quality of the toolbox matter even more. Every new CUDA-X library is effectively a new skill for every science agent built on the Nvidia stack. That’s the competitive moat that AMD, Intel, and the custom-silicon players have to cross, and it deepened this week.
What research and IT leaders should be doing:
- Measure iterations, not jobs. Benchmark infrastructure by the number of hypothesis-to-result cycles a team can run per day, including data movement, scheduling, and analysis time.
- Start an open-model post-training pilot. The results from Lila, Therna, and Terray suggest that a domain-tuned open model trained on your experimental data can outperform frontier APIs in both accuracy and cost. Pick one narrow, high-value task and test it.
- Plan for heterogeneous scheduling. If quantum is on your roadmap, even in a research capacity, standardize on schedulers and interfaces (Slurm, QRMI, QDMI) that treat QPUs as another resource rather than as a special project.
- Put CPU-bound HPC back on the evaluation list. Arm-based CPU racks are now a viable alternative for climate, CFD and other unaccelerated codes, especially when power is constrained. Insist on testing your own applications.
- Treat the network as part of the science. Optics reliability and latency directly affect agentic workflows. Ask your cloud and infrastructure providers about their co-packaged optics roadmaps.
Final thoughts
Most of the performance numbers at SC26 are Nvidia’s own or those of its partners. Historically, I have found Nvidia’s numbers to be accurate, but buyers should validate them against their own workloads. Several key products, including Rubin HPC and HLRE-5, won’t arrive until 2028.
Every additional layer Nvidia owns, from CPU to scheduler integration to quantum decoding, raises the familiar question of how open an end-to-end stack can be. Nvidia’s response this week was a strong emphasis on open source: open models, open datasets, open libraries, and contributions to Slurm.
The bigger takeaway is the shift in what Nvidia is selling. For 20 years, it accelerated the computations scientists ran. Now it’s building the stack for an agent to run the scientific method itself: reason, simulate, measure, refine and repeat. If that model takes hold, the winners in scientific computing won’t be the companies with the fastest single chip. They’ll be the ones that make the whole discovery loop spin fastest. Right now, no one is better positioned than Nvidia for that.
Zeus Kerravala is a principal analyst at ZK Research, a division of Kerravala Consulting. He wrote this article for SiliconANGLE.
Photo: Nvidia