
AI agents are changing how enterprises create, move and govern information, and data observability is turning into a prerequisite rather than a nice-to-have. Models get most of the attention, but the data beneath them decides whether they hold up in production.
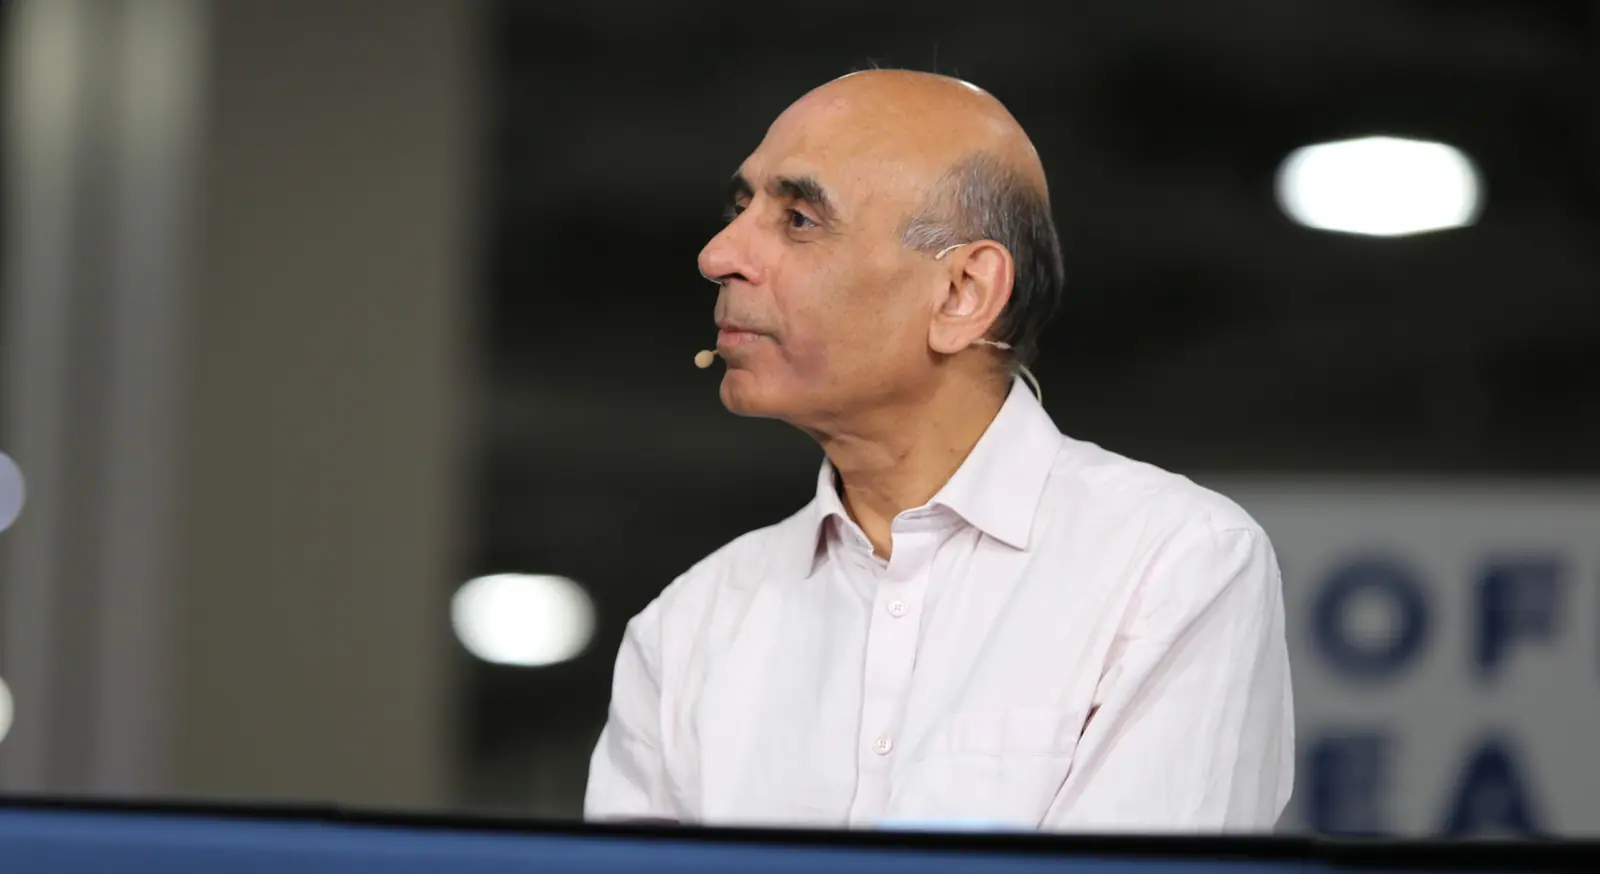
That pressure is now reaching the cloud-native community, where KubeCon organizers added a dedicated AI inference and agentic track this year. The industry has raced from chatbots to retrieval, fine-tuning and agents, yet every wave rests on the same groundwork, according to Sanjeev Mohan (pictured), principal at SanjMo, a data and AI advisory firm, and author of “Designing the AI-Driven Data Foundations.”
“AI can only be successful if it’s built on a solid foundation,” Mohan said. “You have no observability or transparency into it. No matter what you do on top of it, it will not be successful.”
Mohan spoke with theCUBE Research’s John Furrier and Rebecca Knight at KubeCon + CloudNativeCon NA, during an exclusive broadcast on theCUBE, SiliconANGLE Media’s livestreaming studio. They discussed theCUBE’s second day of coverage at the event. (* Disclosure below.)
Why AI agents demand data observability at runtime
For decades, data was created once in an operational system and then pushed through brittle pipelines for extraction, transformation, cataloging and preparation. That model works when humans consume batch reports, Mohan explained. Thousands of agents change the math.
“They’re not going to wait for this pipeline to finish. They want access to the database directly,” Mohan said.
Agents are also doing something no earlier software did. They spin up short-lived databases, copy data and test different chains of thought before picking one action, according to Mohan. An agent reviewing a loan application might query census records and social media before rejecting it, which raises the question of how that decision gets audited.
“Governance becomes really important, and this is not like governance in the past where you would govern your data and then have a deterministic CFO report dashboard run on it,” Mohan said.
That makes data observability part of the architecture itself, not an afterthought bolted onto a warehouse. Mohan’s book, published in June 2026 by John Wiley & Sons Inc., examines how AI agents as first-class data consumers are redefining architectural principles that have stood for decades. Future platforms will need to blend structured and unstructured data in a single converged system, he noted.
“You have to save the state and you have to build the context, and this context is being built in runtime,” Mohan said. “The context for the same task could be very different for the three of us. So we’ll see new kinds of databases.”
Stay tuned for the complete video interview, part of SiliconANGLE’s and theCUBE’s coverage of KubeCon + CloudNativeCon NA.
(* Disclosure: TheCUBE is a paid media partner for KubeCon + CloudNativeCon NA. Sponsors of theCUBE’s event coverage do not have editorial control over content on theCUBE or SiliconANGLE.)
Photo: SiliconANGLE