
AI spending is shifting from giant training clusters toward smaller, quickly built sites, and modular data centers are becoming a natural home for inference workloads. Power, cooling and memory supply now shape where tokens get generated as much as raw chip performance does.
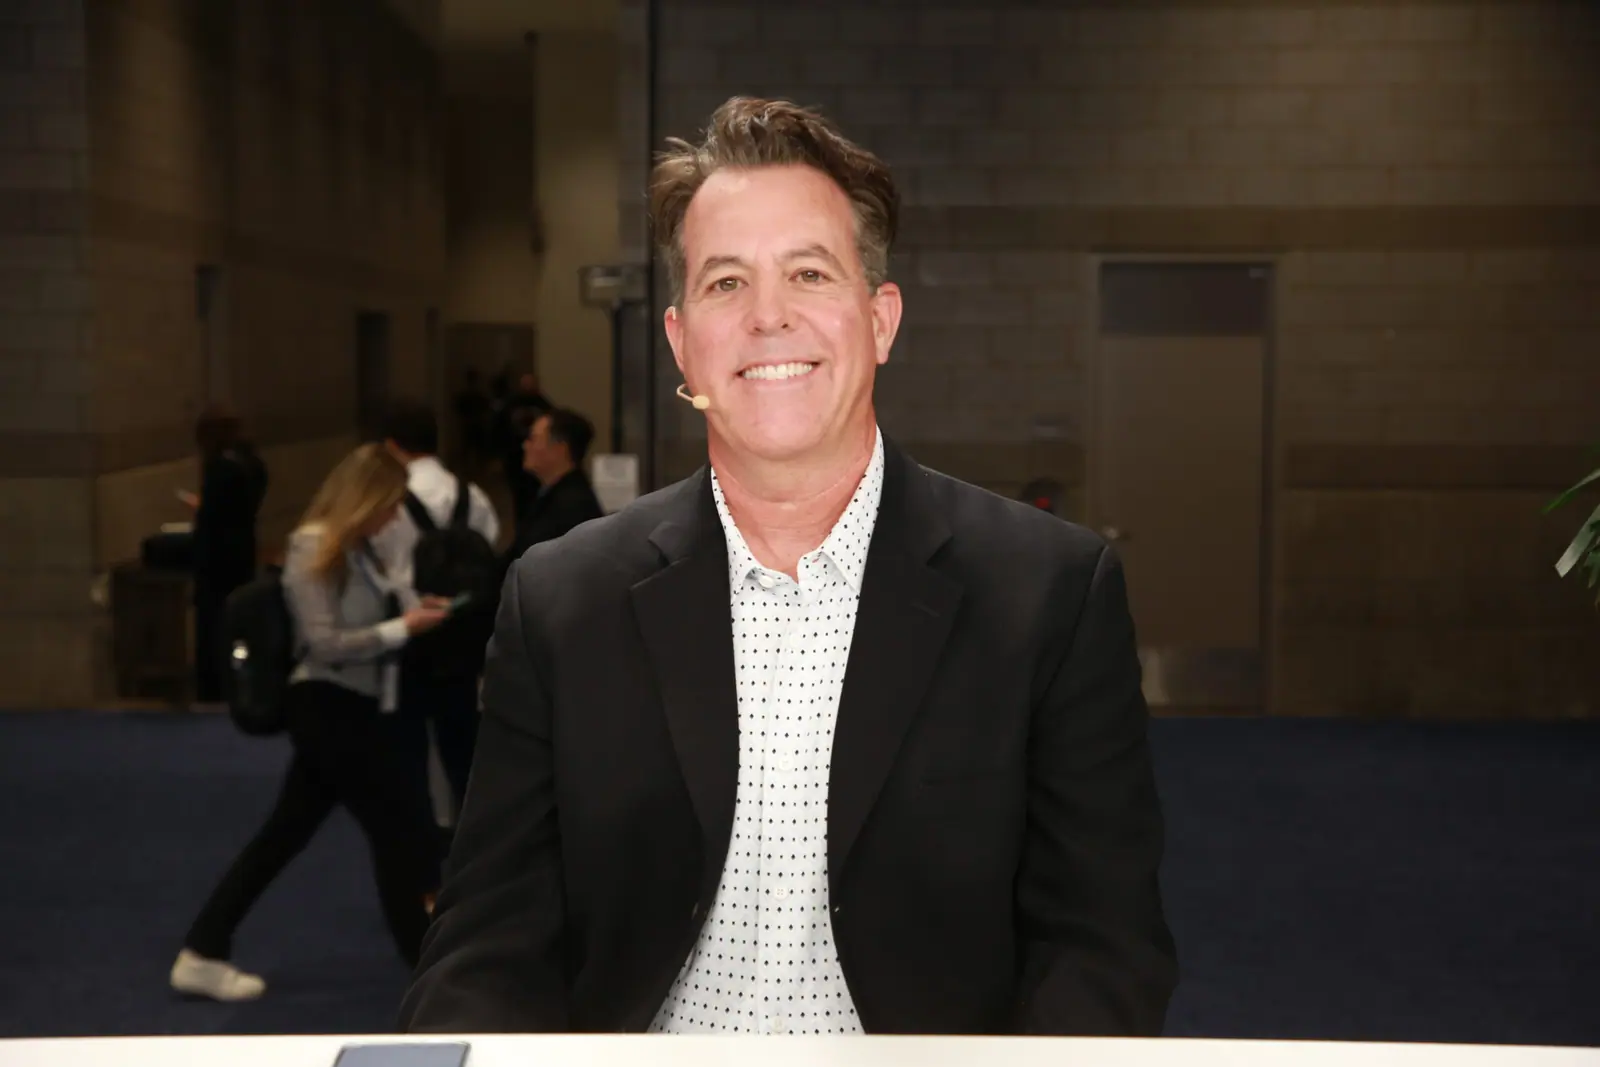
Inference-first chipmakers want to capture that shift. Positron AI Inc., which raised $875 million at a $5 billion valuation in September, builds inference appliances around commodity memory instead of scarce high-bandwidth memory. Inference has overtaken training as the force behind infrastructure buying decisions, according to Cameron McCaskill (pictured), head of sales and business development at Positron.
“We’re at a point where about two-thirds of the workloads being run through these AI infrastructures are inference versus one-third is training. And back in 2023, it was like 85% training, 15% inference,” McCaskill said. “So now you can see why inference is driving the economic decisions of how they’re going to build out their infrastructure.”
McCaskill spoke with theCUBE Research’s Rebecca Knight and John Furrier at SC26, during an exclusive broadcast on theCUBE, SiliconANGLE Media’s livestreaming studio. They discussed inference overtaking training, Positron’s commodity-memory chip design and why low-power modular data centers suit inference. (* Disclosure below.)
Why modular data centers suit low-power inference
Positron’s first-generation Atlas server ran on a programmable chip, and the company plans to tape out its own silicon early next year for its Titan server. Oracle Corp. is bringing about 340 Atlas servers live in its cloud this quarter, McCaskill noted. A neocloud provider has also signed on for Atlas and committed to Titan. Positron’s central design choice was skipping high-bandwidth memory.
“Everyone else pretty much in the industry is using what’s called HBM or high bandwidth memory. It’s very limited in supply, very expensive,” McCaskill said. “We went with commodity memory.”
That choice also keeps power low enough for air-cooled rooms. A single Positron server draws about 4,500 watts, and a full rack of Titan servers fits within 40 kilowatts, McCaskill explained. That footprint suits sites where operators can find a few megawatts of cheap power without heavy regulatory hurdles. For inference providers monetizing new capacity, deployment speed is a big part of the appeal, according to McCaskill.
“One of the groups of companies that we’re seeing a rise in right now and coming to us for product is these modular data centers, where they have a half megawatt or, 1 megawatt or 2.5 megawatt modular data center, and those can be deployed very quickly,” McCaskill said. “And the goal of a lot of these inference players is I want to get from land and power to monetizable tokens within 90 to 120 days. And those modular data centers, coupled with our technology, can be a great solution.”
Here’s the complete video interview, part of SiliconANGLE’s and theCUBE’s coverage of SC26:
(* Disclosure: NYSE Wired sponsored this segment of theCUBE. Neither NYSE Wired nor other sponsors have editorial control over content on theCUBE or SiliconANGLE.)
Photo: SiliconANGLE