
MarkTechPost AI Full text
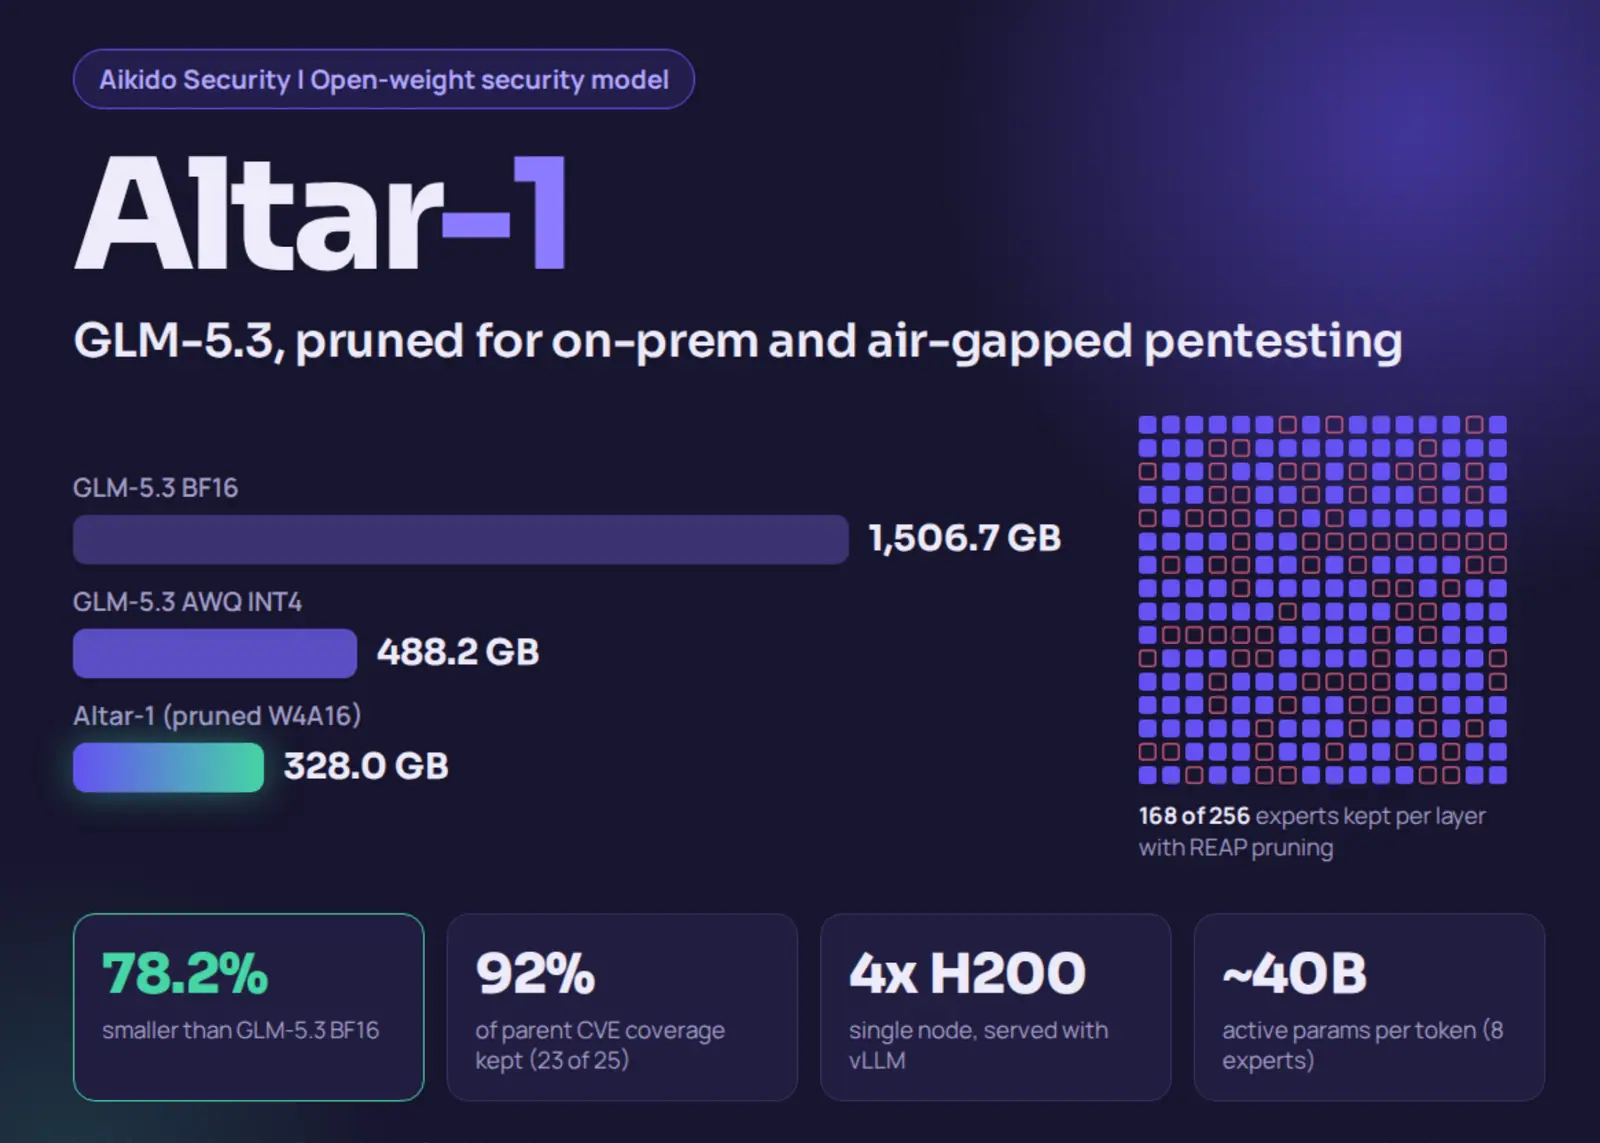
Aikido Security Releases Altar-1: An Open-Weight Security Model Pruned From GLM-5.3 to 328 GB
Aikido Security's Altar-1 compresses GLM-5.3 from 1.51 TB to 328 GB, runs on 4x H200 for on-prem pentesting.
The financial desks we read, gathered in one place. Stories we are licensed to carry are reproduced in full with the writer credited; everything else is a headline and a short quotation that links straight to the publisher.
MarkTechPost AI Full text
Aikido Security's Altar-1 compresses GLM-5.3 from 1.51 TB to 328 GB, runs on 4x H200 for on-prem pentesting.
MarkTechPost AI
MarkTechPost AI
MarkTechPost AI
MarkTechPost AI
MarkTechPost AI
MarkTechPost AI
MarkTechPost AI
MarkTechPost AI
MarkTechPost AI
0sec Labs has open-sourced 0, an AI security harness for code review, pentesting, reverse engineering and fixes. It runs locally through a browser console, a headless CLI and an MCP server, with your own model provider…
MarkTechPost AI
Google's Elephant-Goldfish Model plugin makes coding agents draft specs, then runs 5 zero-context review stages before any code. The post Google AI Releases Elephant-Goldfish Model Plugin for Spec-First Coding appeared…
MarkTechPost AI
A config-verified comparison of how 10 open MoE models route tokens: total and active parameters, expert counts, top-k, shared experts, gating functions and load-balancing methods. The post Which Routing Does Each MoE…
MarkTechPost AI
MoE routing strategies decide which experts process each token. This guide explains 7 methods, from Mixtral's top-2 softmax to DeepSeek-V4's hash routing, with the models that use each one. The post MoE Routing…
MarkTechPost AI
Nous Research released Arete-27B, an Apache 2.0 fine-tune of Qwen3.8-27B. On Nous’s 803-prompt eval, propaganda answers fell from 22% to 0.9% while Hermes Bench stayed flat at 65.60%. The post Nous Research Releases…
MarkTechPost AI
Explore a comprehensive coding guide for NVIDIA's Dory 1.0 4B looped language model. Learn how to build the pinned llama.cpp branch, analyze loop-by-loop compute costs, test memory caching, and run paired evaluations…
MarkTechPost AI
Buoyant has released Kinference, an Apache 2.0 inference control plane for vLLM on Kubernetes. It adds declarative routing policies, KV-cache-aware load balancing and per-tenant metrics, and cut median TTFT 95% in…
MarkTechPost AI
Zyphra released ZYFA, open-source FP8 and BF16 prefill attention kernels for AMD Instinct MI355X. On real model activations, its FP8 kernels run 1.16-1.76x faster than AMD’s AITER, with 62-78% lower error at head…
MarkTechPost AI
Thinking Machines Lab released Inkling 2 Small, a 594B-parameter MoE with 17B active parameters. It scores 31 on the Artificial Analysis Intelligence Index and runs on Tinker, with Apache 2.0 weights planned. The post…
MarkTechPost AI
Google released Gemini Omni 1.2 Flash, a video generation and editing model with native 15-second clips, multi-turn conversational editing and a 30% price cut to $0.07 per second of 720p video. The post Google Releases…
MarkTechPost AI
Baidu has released ERNIE 5.5 Flash Base, a 280B sparse MoE base model with 14B active parameters, trained on 33.5T tokens and published before any mid- or post-training. The post Baidu Releases ERNIE 5.5 Flash Base: A…
MarkTechPost AI
Together AI released Together Compiler, an agent-driven loop that keeps re-optimizing the inference forward pass as traffic shifts. It beat the best InferenceX configurations by up to 2.6x TPS in under 24 hours per…
Stories marked Full text are reproduced here under the terms their publisher allows, with the writer credited and the original linked. Everything else is a headline and a short quotation that links straight to the publisher. How we quote · Our sources